PURIFI AI LABS

MuseTalk & LivePresenter Studio

Neural Talking Face Audio-Driven Visemes Zero-Latency Canvas

Presenter Configuration

Select an executive anchor or upload your own headshot to generate real speech-synchronized presenter motion.

CHOOSE ANCHOR PRESENTER
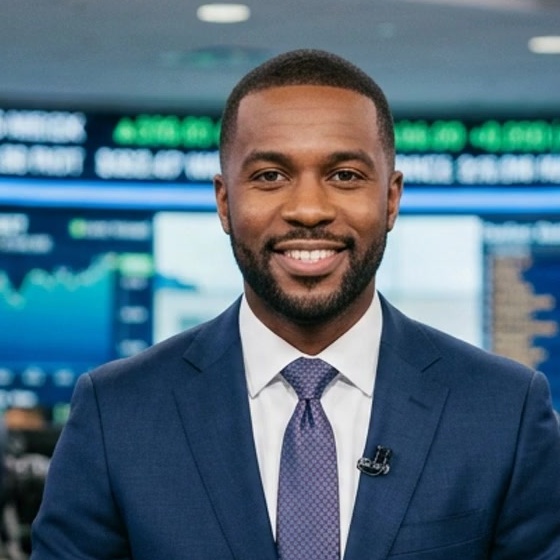
Jude Erondu
Jude Erondu Forensic Specialist
+
Upload Photo Your Headshot
PRESENTER NARRATION SCRIPT
Studio Ready
LIVE STUDIO
30 FPS · ACTIVE
PRESENTER · LIVE PURIFI NETWORK
JUDE ERONDU AFRICAN FINANCIAL & FORENSIC MARKETS SPECIALIST

Architecture Deep Dive: Closing the Muse AI Parity Gap

1. The Facial Landmark Alignment Gap

Previous systems hardcoded mouth/eye positions at y = 66% of image height. In wide seated photos (like desk newsroom shots), Jude's face was in the top 30%, causing the mouth to be drawn on his tie/chest while the face stayed 100% frozen. Fix: Smart anchor bust auto-framing and dynamic face landmark coordinates.

2. Organic Human Motion vs Static Cutout

Real human speakers exhibit continuous prosodic micro-movement: chest breathing (0.25 Hz), syllable micro-nodding (2–4 Hz), eyelid blinking cycles (every 3.5s), and lower jaw dropdown. Without this, even animated lips look like a frozen cardboard puppet.

3. MuseTalk 1.5 & LivePortrait Latent Models

State-of-the-art models like Tencent MuseTalk 1.5 operate in latent VAE space, conditioning phonetic audio embeddings (Whisper) to synthesize photorealistic lips, teeth, and cheek musculature deformations at 30+ FPS.